
Provocation
GovTech showed its working. The interesting part is what it can afford.
GovTech's AIDE model, the tools that make it safe, and why the assembly cost falls hardest on teams without a central data practice.
On 27 August, at the STACK Meetup [Data] in Punggol, GovTech Singapore's Data Practice showed its working.
On 28 August, at Suntec, it launched the Standard Data Platform: five golden paths onto Databricks, Snowflake, Microsoft, AWS and Google Cloud, with Microsoft Fabric carrying Singapore data residency.
Two days, two halves of one programme: the platform underneath, and the operating model on top of it.
You can watch the session recording on GovTech's event page.
It is very good, and it is built for government and the GLCs. So what happens everywhere else?
What they showed
Dr. Ghim-Eng Yap, who runs the Data Practice, set the frame. The government does not have a talent shortage.
His words: "we don't lack data engineering talent, we need to enable our people to achieve even more for public good by adapting our workflows to leverage AI."
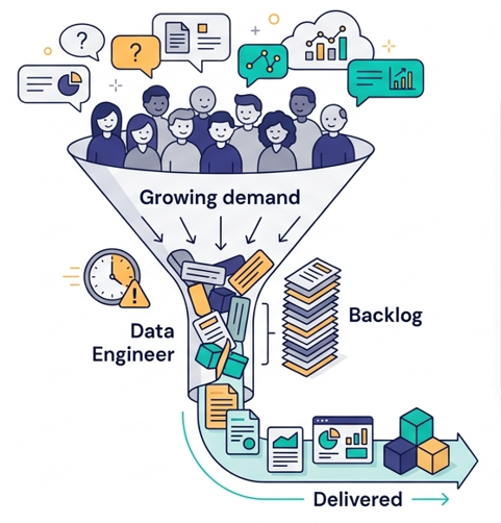
GovTech's own picture of the bottleneck, from "Breaking the Bottleneck: How Human-AI Collaboration is Reshaping Data Engineering", 22 July 2026. Reproduced with attribution.
The move he describes is not faster typing. I am no authority on typing speed, having still not joined the whisper-flow revolution and continuing to enter text by hand, like a Victorian.
It is an answer to what Janice Ng called the "translation tax" between domain experts and data engineers.
The experts know the rules, the edge cases and what good looks like, but cannot write production code. The engineers can build pipelines, but cannot absorb every domain at the required rate.
The operating model breaks at that seam. Requirements become documents and tickets. Engineers interpret, clarify, iterate and occasionally guess. The queue grows with every hand-off.
Then Janice changed how the rest should be read: "AIDE is not a tool. It is a model."
AIDE, AI for Data Engineering, shifts the work from manual transcription to AI-assisted co-creation. Janice laid it out as four pillars. Their wording, not mine.
- Intent-driven data engineering, where the end goal guides architecting.
- Contract-First Co-Creation.
- Human-in-the-Loop, "always", because "humans develop the blueprint while AI lays the bricks."
- Policy-as-Code Assembly, where "speed isn't enough, trusted speed i.e. speed with governance is the aim."
The slogans travel well. The mechanism underneath is the part worth copying, and GovTech has written it up themselves.
A data user brings a Golden Dataset: in Janice's talk, sample data rather than production data, with no more than ten records showing what good looks like.
An agent drafts a machine-readable data contract from it. The contract carries the schema, quality rules and governance expectations, with government policy built in before pipeline assembly begins.
That contract becomes a test suite. The loop exposes missing requirements, repeats until the contract holds, and only then lets AI build the pipeline and adjust it until the tests pass.
Then the number. At the meetup it was one QA architect governing twenty AI-generated pipelines, with data engineers inverting from eighty per cent building to eighty per cent review and standards.
GovTech's written account is more careful. AIDE began as a proof of concept. Early results are promising. One engineer can support several initiatives at once.
Read twenty as the shape of the bet, not a number already banked. It remains the most interesting figure anyone in Singapore has put on this.
In the Q&A, Janice also drew the boundary. The workflow shown covers building pipelines that put data into the repository. Consumption and access control sit later. She described production observability as the next stage.
Debananda Ghosh from Microsoft took the consumption side. His argument was that ontology gives agents shared business meaning and improves answers to complex questions.
Our work sits beneath that semantic layer, in the physical foundation that feeds it. Microsoft publishes skills for Fabric, and Studio accepts user-added plugins today.
Michael Han of Infinite Lambda followed with Mandai Wildlife Group's move from a legacy on-premise warehouse to cloud within a year.
He put his own leverage figure on it. His team built seven apps in the time it would normally take to build one or two. Later, he said two or three became useful by reaching production or driving an outcome.
The unused prototypes still produced evidence. One justified buying a feedback tool instead. AI had made prototypes cheap enough to use for discovery rather than defend as miniature products.
Reconcile a changed number with its owner before it reaches a dashboard. Otherwise, "You have lost trust. You cannot recover the trust for your new initiative."
AI compresses the time to insight and decision-making. The decisions and operational ownership stay with people. "It's an adoption problem and not a build problem."
The four things they had to build
On 6 August I counted fourteen hand-built components in one Microsoft principal engineer's harness.
Expecting every data team on earth to assemble the same fourteen seemed an odd way to run an industry.
GovTech's list runs to four, and the length is the point. Four pieces of tooling had to exist before the four pillars would carry any weight.
- Test case generation
- Data contract generation
- Data pattern building
- Synthetic data with PII shielding, so production records never reach a model
There is a fifth, and they gave it away. VOWL validates Open Data Contract Standard contracts against real data once a pipeline is live.
It is MIT-licensed and on GitHub. That generosity matters, but it does not turn the other four into configuration options.
Those are small products. Each arrives with a roadmap, a maintainer and a support burden. GovTech ended up owning four because that was the shortest path to the operating model it wanted.
Different institution, different half of the stack, identical conclusion. Nobody sells this whole, so we built it.
One to twenty is not a productivity statistic
It is a statement about what the reviewer is permitted to skip.
At twenty pipelines, a human cannot read everything. They can read what the system has already refused to let through.
The ratio therefore holds exactly as far as the gates are mechanical, and not one pipeline further.
Make the gates advisory and one-to-twenty becomes one person nodding at twenty things they have not read. That is not governance. It is a signature.
Michael's operating rules came from the reconciliation work at Mandai.
The goal must be machine-checkable. Iterations must be bounded. The agent must not change its tests. When it cannot make the evidence agree, it needs an escalation path rather than another turn.
One rule closes the loophole: "The agent can never redefine what is correct."
Janice drew the same line from the other side. She would not let AI do computational work probabilistically when people will use the answer to make decisions.
For data retrieval, her preference was explicit: deterministic rather than probabilistic.
Two speakers, two ends of a lifecycle, one evening, one refusal. The agent builds the machine. The machine stays deterministic. Trust arrives as evidence rather than tone.
The fashionable answer runs the other way.
Put the model inside the running system, where it demos magnificently and reasons freshly about your revenue figure at two o'clock every morning.
It lands on a slightly different answer each time and delivers all of them with total confidence. GovTech has, rightly, declined to do this.
What about everyone else
A government agency or GLC now has a standardised platform, five vetted paths, Fabric with local residency, a central Data Practice, bespoke tooling, contracts on an open standard and a ratio with a number.
That is serious institutional engineering. It was built for the public service by people whose job is the public service, and the agencies should have it.
GovTech has also been unusually generous. The AIDE write-up is public and detailed. It says the principles "aren't exclusive to government" and ends with six tips for applying them.
VOWL is on GitHub under MIT. This is an agency doing nearly everything an agency can do to give the work away, and more than most private vendors would.
It still leaves you building it.
Six tips and a validation engine are an excellent description of a destination and a genuinely useful component. They are not a thing a team can adopt on Monday morning.
The rest of the economy wants the same result and starts from somewhere else.
The family-owned logistics group would also like trusted speed. So would the Tuas manufacturer, the mid-sized insurer and the regional integrator carrying eight clients without a central practice.
They do not lack ambition. They lack the four tools, and the year it takes to build them.
The cost of that year is regressive. GovTech pays it once and spreads it across the government. A forty-person data team pays the same bill for one team. The integrator pays it per client.
The build is only the first invoice. You keep paying when models change, the harness shifts and platform APIs move on different schedules.
The smaller you are, the larger the share of engineering capacity it eats, and the less likely you are to start at all.
Which is a strange place for an industry to have arrived, given that the whole promise was leverage.
What we are building
Vibedata is your data engineering agent.
The harness around it provides the four things a general coding agent lacks for data work: isolation, guardrails, context and cross-platform reach.
Gates are what make a ratio real, and a gate is not the same thing as a good intention. Ours begins with the Semantic Branch.
A Semantic Branch is the working world for one Intent. It branches the conversation, code, artifacts and an ephemeral workspace on the data platform, rather than merely branching a repository.
The agent works inside that world. Reads can resolve to live data, but the write path to production is absent. No principal the agent can reach holds write access on the production resource.
The mechanism is native to each platform. That is the honest way to put it.
Permissions alone were not enough. A CREATE TABLE on a colliding name can report success and write nothing. The shortcut is removed before anything can write that name.
Somebody found that out the hard way. Now nobody else has to.
Nothing ships itself. Work leaves as a proposed change. Production deployment stays in your own CI/CD, where it belongs, and the agent has no route around it.
Review gates sit on top: approved design by default, independent evidence for acceptance checks, and hard stops for ship approval, destructive schema change and design approval.
They are the second line, not the first. Being wrong is survivable before anyone reviews anything. The agent does not get to redefine correct because it is in a hurry.
That is the difference between a review ratio you can operate and one you can only put on a slide. Twenty pipelines are survivable when being wrong is cheap.
We run on DuckDB (local), Microsoft Fabric and MotherDuck today.
Vibedata is homegrown, born and built in Singapore. Not a moral claim, only an explanation of why the region's problems are the ones we picked first.
GovTech built those four tools because nobody was selling them. That was the right call, and a heavy one. Our argument is that you should not have to make it.
Sandbox provisioning is live. It is a hosted DuckDB environment with your own demo domain, GitHub repository and three worked examples.
Sign in with GitHub and you are provisioned. Spend an evening in it, and tell us where our thinking is wrong.
The four tools are buildable. The year is not refundable. Which are you spending yours on?
References
- GovTech Singapore, "Breaking the Bottleneck: How Human-AI Collaboration is Reshaping Data Engineering" — TechNews, 22 July 2026.
- GovTech Singapore, STACK Meetup [Data], "Data Standards that Scale: AI-enabled Data Engineering" — event page and recording, 27 August 2026.
- VOWL — GovTech Data Practice's MIT-licensed validation engine for Open Data Contract Standard contracts.
- GovTech Singapore, Standard Data Platform launch, "Five Golden Paths to a Standardised Data Landscape" — 28 August 2026, Suntec Convention Centre.
- Open Data Contract Standard v3.1.0 — Bitol, LF AI & Data Foundation.
- Accelerate Data, "The AI-native data engineer is real. Microsoft just published the bill of materials." — 6 August 2026.
- Accelerate Data, "Do you have a harness for your data platform?" — 30 July 2026.
Get the next post by email
One email for each new post — the same Proof, Provocation and Practice writing that is on this page, and nothing else. No product announcements, no event invitations, and no list sharing.
Not wired The subscribe form is markup only in this prototype. No address is captured, and no confirmation email is sent.